Vibe genes? Natural(ish) language comes to protein, genome design software
You can apparently now tell AI tools what sort of protein you want them to make.
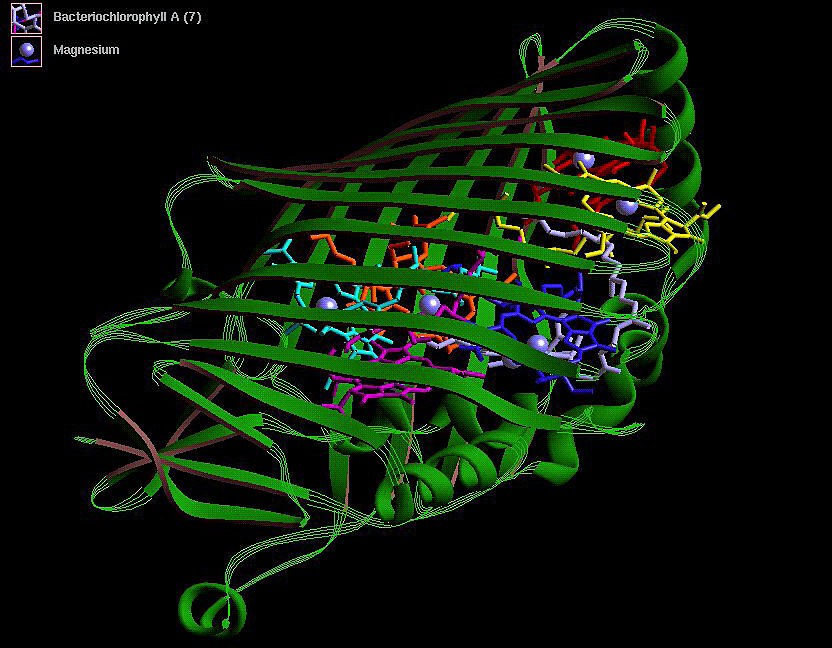
Designing variations of the complex, three-dimensional structures of proteins has been made a lot easier by AI tools. Credit: Historical / Contributor
Protein design tools may be getting increasingly sophisticated, but you still need a sophisticated understanding of protein structure for them to work. This can include knowing enzyme mechanisms down to the positions of specific amino acids, as well as the water molecules that also occupy the area where catalysis takes place. Once you specify these, the tools can build the rest of a protein around this target.
A large collaboration of researchers based in China, however, decided to bring protein design to the masses, making a tool that can take natural language prompts and use them to produce proteins with the function you specify. If your measure for success is a working protein, then the success rate may not be great. But they still manage to get the job done. And, in a separate announcement, Hugging Face shared that it’s now hosting a tool that does similar things on the DNA level.
The equivalent of vibe coding may have come to protein design—at least if you have access to a lab where you can sort the good designs from the dozens of failed ones.
Focusing on function
Some of the best protein design tools we have available right now work through a two-step process. First, you specify a set of constraints, such as the need to bind another molecule or to have a specific arrangement of amino acids. One AI tool then generates the shape of a protein that can meet those constraints. Once that’s done, a separate tool goes through and populates that shape with a specific sequence of amino acids that can ensure the protein folds into the appropriate configuration to match the shape.
Obviously, doing that often requires that you know a fair bit of technical information. If you’re designing a catalyst, for example, then you not only need to know what amino acids are critical to get a chemical reaction to happen, but you have to know where they should be located within a 3D space. That, not surprisingly, requires a fairly sophisticated understanding of protein chemistry and the ability to express that understanding in whatever form that the protein design tools require.
The thing is, if two experts were talking to each other, they wouldn’t need to get that specific. If one said “serine protease,” for example, the other would know a lot of what was implied by that in terms of the specifics of the reaction mechanism. We need to get specific when communicating with an AI tool because, while our current generation of tools are great at working through the 3D arrangements of amino acids, they’re kind of stupid about the functions that those 3D arrangements enable.
In the work of the team behind the new tool, called Pinal, this doesn’t necessarily have to be the case. We have databases full of millions of protein sequences tagged with notes about the functions those proteins perform. With the proper training, the researchers reasoned, it should be possible to just use the same terminology in those tags to get a system that outputs a sequence that performs exactly like what you’re looking for.
Proteins plus language
Pinal on some levels actually works quite like the standard tools, following a two-step process of building a backbone for the protein and then filling in the details of the amino acids that populate that backbone through a separate process. But there are very significant differences—beginning with what you need to do to start the process.
Rather than specifying some details of a few amino acids in the design product, you simply tell the system what you want. “The first stage is handled by T2struct, a text-to-structure module that translates a natural language prompt into a structural blueprint,” as the system’s developers describe it. T2struct doesn’t output a 3D shape, either; it simply produces a linear array of tokens that correspond to the spatial relationship between each amino acid and its nearest neighbors and assign a probability to each.
That gets handed off to a system called SAProt-T, which uses a combination of the original text and the output to T2struct to construct the sequence of amino acids in the final protein design. Here, the probabilities generated earlier matter, since SAProt-T performs a global re-evaluation. According to the authors, this avoids the risk of “overlooking a slightly less probable structure that can accommodate a far superior functional sequence.”
How do you develop a system that can do all of this? The researchers decided the best way was to use massive amounts of data. For each set of tags that describe a protein’s function, they fed the tags into an LLM and had it provide a plain-language description and used both the tags and the description as part of the training. They used protein sequences from three different databases, paired with structural information predicted by AlphaFold; just one of these databases contained 800 million keyword–protein pairs.
It’s noteworthy that AlphaFold is not 100 percent accurate in its predictions, so if you’re trying to generate something related to a relatively obscure protein, this could be a problem. But many common proteins have actual structural data available, which presumably would ensure AlphaFold made informed predictions.
In any case, apparently enough of the structural data was right for the training to work.
Functional proteins
To test Pinal, the researchers asked it to design four very different proteins: a fluorescent one, two enzymes, and one that takes part in a large multi-protein complex. While the details vary a bit from case to case, there was a similar process for each; we’ll use the fluorescent protein as an example.
The classic example of a fluorescent protein, which won its discoverer a Nobel, is GFP, the green fluorescent protein. Pinal was asked to produce 50,000 proteins that could fluoresce like GFP. This massive list was then filtered down by a number of criteria. For starters, the researchers rejected anything with a sequence that looked like a known fluorescent protein. But they selected for a couple of key features found in GFP: the ability to form a barrel-like structure, and the presence of a key amino acid that can be chemically modified to enable fluorescence.
In short, they wanted it to be a bit like GFP in general, but not very similar in terms of the specific amino acid sequence. That filtering left them with a high-priority list of just 29 candidate proteins, all of which were made in E. coli. A grand total of one of them fluoresced.
All of the other examples were done similarly: start with a massive list, narrow it down computationally, then test a few dozen designs, of which only a few would work.
It would be tempting to dismiss this as a horrifically low success rate. But remember that a lot of the suggestions that were most likely to work would look a lot like known GFP proteins, and so be weeded out. The researchers also didn’t even bother to test whether things that didn’t form a structure similar to GFP might work, so they may have rejected a huge range of alternative fluorescent proteins based on that.
Not just proteins
Last week also saw the introduction of something very similar but focused on DNA sequences. A collaboration of the AI company Hugging Face, the Zhongguancun Academy, and the University of Naples “Federico II” introduced what they’re calling Carbon X, an open-weight model that can be run on local hardware. It is based on a human-language model called Qwen3-14B but was retrained using DNA, followed by reinforcement learning and supervised fine-tuning.
The re-training (technically termed mid-training) required a careful balancing act: “A low learning rate preserves English but leaves DNA at chance, and a high one learns DNA but forgets English.” But the result is a single model that can speak both DNA and English and translate between them. So, like large genome models, you can prompt it with a DNA sequence, and it will attempt to predict sequences that might come after it in a typical genome. But you can also prompt it with a mix of DNA and natural language, asking it things like “what would the consequence of changing this G to an A be?”
While the team has not released a publication describing the behavior of the system, their internal performance suggests it’s quite good, being competitive with large, specialized commercial models like GPT-6.1 Sol. That said, it also includes a few cautions. The system is not especially good at noting specific positions, especially on longer sequences. It also can be prone to hallucinations if the prompt isn’t specific enough. So, the usual cautions when using an AI tool definitely apply.
Hugging Face points out two major reasons why Carbon X might be a better option than commercial models, even for tasks where the commercial models tend to perform a bit better, both of them related to the fact that Carbon X can be run locally. The first is simply cost; the company’s demonstration video was done using a MacBook, so it can be run repeatedly on relatively affordable hardware. The second is that there are many situations where, for proprietary or privacy reasons, people will not want to share the inquiries they’re making with a commercial entity.
Keeping it plain
It’s easy to think that this is dumbing biology down so that anybody with the slightest bit of knowledge can now start making custom proteins and viruses. That’s not entirely accurate. They can easily get the sequences out of the tool. But they will then likely need to use a lot of specialized tools to screen through these in order to find sequences that are more likely to be functional. And then there’s the issue of testing them, which requires a well-equipped biology lab and trained specialists.
Biologists have clearly not been taken out of the equation.
And in many cases, this may solve some ongoing issues faced by experimental biologists. In the post-genome era, there have been lots of questions that are best answered via computer. But a lot of tools made to get these answers were made by bioinformaticians who did not go out of their way to make their tools approachable. Many biologists can understand a relatively English-ish phrase like “find me all the enhancers that control the expression of this gene.” But far fewer will know which combination of tools are needed to answer that question, much less how to configure them.
Giving those biologists a tool that can answer these questions without the need to consult multiple software manuals has a real potential to accelerate research. But it may take a few years before it becomes clear that biologists find this capability useful.
Nature, 2025. DOI: 10.1038/s41586-026-11205-z (About DOIs).
John is Ars Technica's science editor. He has a Bachelor of Arts in Biochemistry from Columbia University, and a Ph.D. in Molecular and Cell Biology from the University of California, Berkeley. When physically separated from his keyboard, he tends to seek out a bicycle, or a scenic location for communing with his hiking boots.
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Wow
0
 Sad
0
 Angry
0
Comments (0)